ثبت نام / ورود
0
ثبت نام / ورود
0
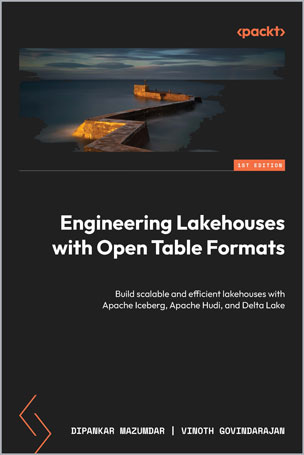
Build scalable and efficient lakehouses with Apache Iceberg, Apache Hudi, and Delta Lake
Dipankar Mazumdar. Vinoth Govindarajan
#Engineering
#Lakehouses
#Apache_Iceberg
#Apache_Hudi
#Delta_Lake
#XTable
#UniForm
#MLflow
#TensorFlow
🏗️ مهندسی Lakehouseها با Open Table Formatها
🚀 مسیر تسلط روی الگوهای معماری Open Data رو با یادگیری مبانی و کاربردهای Open Table Formatها شروع کن.
✨ ویژگیهای کلیدی
🗃️ با استفاده از Open Table Formatها و Compute Engineهایی مثل Apache Spark، Flink، Trino و Python، Lakehouse میسازی
⚙️ Lakehouseها رو با تکنیکهایی مثل Pruning، Partitioning، Compaction، Indexing و Clustering بهینه میکنی
🔗 یاد میگیری چطور با Apache XTable یکپارچهسازی روان، مدیریت داده و Interoperability بین فرمتهای مختلف رو فراهم کنی
📘 توضیح کتاب
🧠 کتاب Engineering Lakehouses with Open Table Formats دیدی عمیق و کاربردی نسبت به مفاهیم Lakehouse ارائه میده و بعد وارد پیادهسازی عملی Open Table Formatهایی مثل Apache Iceberg، Apache Hudi و Delta Lake میشه.
🔍 ساختار داخلی Table Formatها رو بررسی میکنی و با جزئیات یاد میگیری قابلیتهای Transactional در Lakehouseها چطور کار میکنن. همینطور با هر Table Format بهصورت عملی کار میکنی و تمرینهایی با Compute Engineهای محبوب مثل Apache Spark، Flink، Trino و ابزارهای مبتنی بر Python انجام میدی.
⚙️ کتاب سراغ موضوعهای پیشرفتهای مثل تکنیکهای بهینهسازی پرفورمنس و Interoperability بین فرمتهای مختلف هم میره تا بتونی Lakehouseهای آماده پروداکشن بسازی. توضیحهای قدمبهقدم کمک میکنن کامپوننتهای اصلی معماری Lakehouse رو درک کنی و یاد بگیری چطور اونها رو بسازی، نگهداری و بهینه کنی.
🎯 تا پایان کتاب، میتونی Open Table Formatهای مختلف رو ارزیابی و پیادهسازی کنی، پرفورمنس Lakehouse رو بهینه کنی و این مفاهیم رو در سناریوهای واقعی به کار بگیری تا برای نیازهای دادهای سازمان خودت، معماری مناسبتری انتخاب کنی.
🎯 چیزهایی که یاد میگیری
🧱 مبانی Lakehouse مثل Table Formatها، File Formatها، Compute Engineها و Catalogها رو بررسی میکنی
🔄 درک کاملی از مدیریت چرخه عمر داده در Lakehouseها به دست میاری
🧠 یاد میگیری چطور بهشکل سیستماتیک Table Format مناسب برای Lakehouse رو ارزیابی و انتخاب کنی
⚡ پرفورمنس رو با تکنیکهای Sorting، Clustering و Indexing بهینه میکنی
🤖 از دادههای Open Table Format در فریمورکهای ML مثل TensorFlow و MLflow استفاده میکنی
🔗 با Apache XTable و UniForm بین Table Formatهای مختلف Interoperability ایجاد میکنی
🔐 با Access Controlها Lakehouse رو امن میکنی و الزامات Compliance رو رعایت میکنی
👤 این کتاب برای چه کسانیه؟
💻 این کتاب برای Data Engineerها، Software Engineerها و Data Architectهایی نوشته شده که میخوان درک عمیقتری از Open Table Formatهایی مثل Apache Iceberg، Apache Hudi و Delta Lake پیدا کنن و ببینن این تکنولوژیها چطور برای ساخت Lakehouse استفاده میشن.
🗄️ همینطور برای متخصصهایی ارزشمنده که با Data Warehouseهای سنتی، دیتابیسهای رابطهای و Data Lakeها کار میکنن و میخوان به سمت الگوهای معماری Open Data مهاجرت کنن.
📌 برای دنبال کردن راحتتر مطالب، آشنایی پایه با دیتابیسها، Python، Apache Spark، Java و SQL توصیه میشه.
📖 فهرست مطالب
فصل ۱. Open Data Lakehouse. یک پارادایم معماری جدید
فصل ۲. قابلیتهای Transactional در Lakehouse
فصل ۳. بررسی عمیق Apache Iceberg
فصل ۴. بررسی عمیق Apache Hudi
فصل ۵. بررسی عمیق Delta Lake
فصل ۶. مدیریت Catalog و Metadata
فصل ۷. Interoperability در Lakehouseها
فصل ۸. بهینهسازی و Tuning پرفورمنس در Lakehouse
فصل ۹. Data Governance و Security در Lakehouseها
فصل ۱۰. ارزیابی و انتخاب Open Table Formatها
فصل ۱۱. کاربردها و تجربههای دنیای واقعی
فصل ۱۲. دسترسی به مزایای اختصاصی
📝 نقد و بررسی
💭 «Analytics و AI عالی، از زیرساخت داده عالی شروع میشن. در کتاب Engineering Lakehouses with Open Table Formats، دیپانکار مازومدار و وینوث گووینداراجان توضیح میدن که Apache Iceberg، Apache Hudi و Delta Lake چطور معماریهای Lakehouse قابلاعتماد و مقیاسپذیر رو ممکن میکنن و همین موضوع این کتاب رو به راهنمایی ارزشمند برای Data Engineerهای مدرن تبدیل میکنه.»
— کریشنا آکوراتی، Director در CVS Health
👤 درباره نویسندگان
👨💻 دیپانکار مازومدار در حال حاضر Staff Data Engineer Advocate در Onehouse.ai است و روی پروژههای Open Source مثل Apache Hudi و XTable تمرکز داره تا به تیمهای مهندسی کمک کنه پلتفرمهای Data Analytics مقاوم و مقیاسپذیر بسازن.
🧩 او پیش از این در Dremio روی پروژههای مهم Open Source مثل Apache Iceberg و Apache Arrow کار کرده. بخش بزرگی از مسیر حرفهای او در نقطه تلاقی Data Visualization و Machine Learning گذشته.
🎤 دیپانکار در کنفرانسهای مختلفی مثل Data+AI، ApacheCon، Scale By the Bay و Data Day Texas سخنرانی کرده.
🎓 او مدرک کارشناسی ارشد علوم کامپیوتر داره و پژوهشهای دانشگاهیش روی تکنیکهای Explainable AI متمرکز بوده.
👨💻 وینوث گووینداراجان متخصص باتجربه داده و Staff Software Engineer در Apple Inc. است و روی پلتفرمهای داده مبتنی بر تکنولوژیهای Open Source مثل Iceberg، Spark، Trino و Flink کار میکنه.
⚙️ او پیش از این در Uber روی طراحی فریمورکهای Incremental ETL برای پردازش Real-Time Data فعالیت داشته.
🌐 وینوث Contributor فعال کامیونیتی Open Source در پروژههایی مثل Apache Hudi و dbt-spark است و تجربه خودش رو در کنفرانسهایی مثل dbt Coalesce و گردهماییهای کامیونیتی Hudi به اشتراک گذاشته.
📝 او چندین مقاله و Blog درباره ساخت Open Lakehouseها منتشر کرده و مدرک کارشناسی Information Technology داره. همچنین چندین مقاله پژوهشی در ژورنالهایی مثل IEEE منتشر کرده.
Jump-start your journey toward mastering open data architectural patterns by learning the fundamentals and applications of open table formats
Engineering Lakehouses with Open Table Formats provides detailed insights into lakehouse concepts, and dives deep into the practical implementation of open table formats such as Apache Iceberg, Apache Hudi, and Delta Lake.
You’ll explore the internals of a table format and learn in detail about the transactional capabilities of lakehouses. You’ll also get hands on with each table format with exercises using popular computing engines, such as Apache Spark, Flink, Trino, and Python-based tools. The book addresses advanced topics, including performance optimization techniques and interoperability among different formats, equipping you to build production-ready lakehouses. With step-by-step explanations, you’ll get to grips with the key components of lakehouse architecture and learn how to build, maintain, and optimize them.
By the end of this book, you’ll be proficient in evaluating and implementing open table formats, optimizing lakehouse performance, and applying these concepts to real-world scenarios, ensuring you make informed decisions in selecting the right architecture for your organization’s data needs.
This book is for data engineers, software engineers, and data architects who want to deepen their understanding of open table formats, such as Apache Iceberg, Apache Hudi, and Delta Lake, and see how they are used to build lakehouses. It is also valuable for professionals working with traditional data warehouses, relational databases, and data lakes who wish to transition to an open data architectural pattern. Basic knowledge of databases, Python, Apache Spark, Java, and SQL is recommended for a smooth learning experience.
“Great analytics and AI start with great data foundations. In Engineering Lakehouses with Open Table Formats, Dipankar Mazumdar and Vinoth Govindarajan explain how Apache Iceberg, Apache Hudi, and Delta Lake power reliable, scalable lakehouse architectures, making this a valuable guide for modern data engineers.”
Krishna Akurathi, Director, CVS Health
Dipankar Mazumdar is currently a Staff Data Engineer Advocate at Onehouse.ai, where he focuses on open source projects such as Apache Hudi and XTable to help engineering teams build and scale robust data analytics platforms. Before this, he worked on critical open source projects such as Apache Iceberg and Apache Arrow at Dremio. For most of his career, he worked at the intersection of data visualization and machine learning. He has also been a speaker at numerous conferences, such as Data+AI, ApacheCon, Scale By the Bay, and Data Day Texas, among others. Dipankar has a master's degree in computer science with research focused on explainable AI techniques.
Vinoth Govindarajan is a seasoned data expert and staff software engineer at Apple Inc., where he spearheads data platforms using open-source technologies like Iceberg, Spark, Trino, and Flink. Before this, he worked on designing incremental ETL frameworks for real-time data processing at Uber. He is a dedicated contributor to the open source community in projects such as Apache Hudi and dbt-spark. As a thought leader, Vinoth has shared his expertise through speaking engagements at conferences such as dbt Coalesce and Hudi OSS community meetups. He has published several blogs on building open lakehouses. Holding a bachelor's degree in information technology, Vinoth has also authored multiple research papers published in journals like IEEE.